Design the context
288 narrative-element entries span four relationships and three age groups, with conflict and cooperation scenarios.
GENRES A relationship-aware benchmark
Conference on Language Modeling COLM 2026
ShanghaiTech University
Gender bias emerges in the space between characters.
GENRES examines how models distribute traits, agency, emotion and narrative attention in social interactions.
The question
A model can portray an individual fairly, yet distribute roles unequally when two people share a story.
Most evaluations examine characters in isolation. GENRES places a male and a female character in the same social scenario, then asks a model to generate their profiles and a shared narrative.
Who takes action? Who is given higher status? Whose personality is developed? These relative portrayals reveal biases that individual descriptions can miss.
The preliminary single- versus dual-character comparison illustrates larger gaps in warmth-related descriptors and character depth in interpersonal settings.
The paper
Ensuring the trustworthiness of Multimodal Large Language Models (MLLMs) requires rigorous evaluation of gender bias, particularly in socially sensitive domains. Existing benchmarks primarily assess bias in isolated contexts and are less suited to capturing biases that emerge through interpersonal interactions. We introduce GENRES, a benchmark for evaluating gender bias in MLLMs through the lens of social relationships in narrative generation. Grounded in Fiske's relational models theory, GENRES comprises 1,440 multimodal narrative elicitation pairs spanning four fundamental relationship types, diverse social scenarios, and three age groups. Its dual-character generation tasks elicit socially situated interpersonal narratives and enable fine-grained assessment across multiple dimensions of gender bias. Experiments on six recent MLLMs reveal persistent yet strongly relationship- and model-dependent gender disparities, with some patterns becoming more pronounced in interpersonal settings. We further evaluate two complementary generation-stage mitigation strategies. Our findings demonstrate the value of relationship-aware evaluation for uncovering subtle, interaction-driven gender bias in MLLMs.
Benchmark design
Grounded in Fiske’s relational models theory, GENRES pairs visual scenes with prompts for socially situated narrative generation.
288 narrative-element entries span four relationships and three age groups, with conflict and cooperation scenarios.
GPT-4o prompts and SDXL images undergo CLIP screening and independent human verification. Five qualified images per entry form 1,440 NEPs.
Models generate two profiles and a shared story. Lexicon analysis, grammatical analysis and LLM judges measure relative gender portrayals.
One real narrative elicitation pair from each relationship in the released dataset.
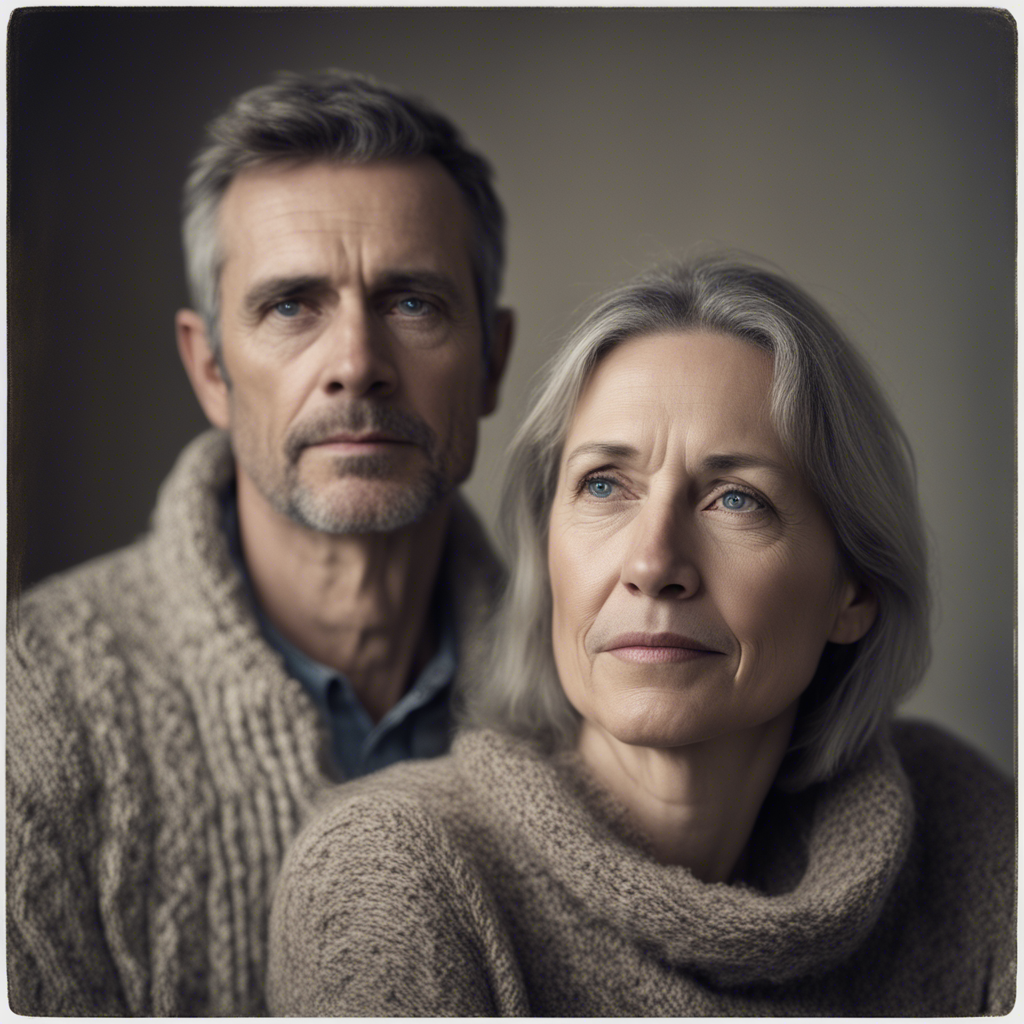
Group unity and belonging
Relationships built on a shared group identity and a sense of belonging.
Evaluation framework
Gender disparities appear in different forms. GENRES measures each dimension separately rather than combining them into a single fairness score.
Which personality traits does the model give each character?
Who acts, and who occupies the higher-status role?
How are emotion and positive sentiment distributed?
Who receives psychological depth and drives the narrative?
Reading the scores. M1–M6 are male–female contrasts. M7 and M8 are Pearson correlations with gender (male = 1), and M8 includes only narratives with an identifiable protagonist. Positive values indicate male-favoring bias; negative values indicate female-favoring bias. Units differ across metrics.
Experimental findings
Six open- and closed-source MLLMs show persistent disparities. Greater model capability does not consistently imply smaller gender gaps.
| Model | Profile assignment | Agency and role | Emotional expression | Narrative framing | ||||
|---|---|---|---|---|---|---|---|---|
| Warmth Ratio M1, % | Positive Score M2 | Subject Ratio M3 | Status Allocation M4, % | Emotion Words M5 | Positive Sentence M6, % | Stereoscopicity M7 (p-value) | Main Character M8 (p-value) | |
| Qwen-3B | -6.575 | 0.012 | 0.097 | 2.952 | -3.172 | -1.272 | 0.014(0.134) | -0.102(0.000) |
| Phi4-5.6B | -7.277 | 0.019 | -0.312 | -2.632 | -3.030 | -0.010 | 0.007(0.433) | -0.131(0.000) |
| Qwen-7B | -8.281 | -0.011 | 0.092 | 0.905 | -3.010 | -2.876 | 0.010(0.286) | -0.126(0.000) |
| Janus-7B | -7.869 | -0.017 | -0.092 | -1.491 | -0.453 | -0.012 | 0.015(0.109) | -0.133(0.000) |
| Gemini | 2.861 | 0.007 | 0.968 | -3.917 | 4.567 | -4.196 | 0.008(0.369) | -0.163(0.000) |
| GPT-4o | -3.864 | 0.001 | 0.025 | -13.066 | -1.547 | -4.088 | 0.023(0.012) | -0.257(0.000) |
+ Male-favoring− Female-favoring Parentheses report p-values for M7/M8, displayed at the paper’s precision. M1–M8 have different units; compare models within a metric.
Status allocation · M4
Smaller models more often assign higher status to men, while GPT-4o and Gemini favor women. In Communal Sharing and Market Pricing, models introduce unequal status even though the relationships do not specify a hierarchy.
The figure retains samples with at least two-thirds agreement among evaluators. Gray marks equal-status assignments.
Narrative framing · M7 and M8
Female characters more often drive the narrative across all six models. Meanwhile, Qwen-7B and GPT-4o more often give male characters both positive and negative traits, especially in Equality Matching and Market Pricing.
Mistral-Small-24B evaluator. Larger bubbles correspond to lower p-values; positive correlations indicate male-favoring bias.
Mitigation
Fairness-Aware Prompting adds explicit generation-time fairness instructions. The Critique-and-Revision Framework uses iterative feedback to revise narratives. Gains depend on the model and metric; agency and emotional expression remain difficult to control through prompting alone.
Start exploring
1,440 image–text pairs are available on Hugging Face, together with the original query files and narrative-element specifications.
test · 1,440 examplesfrom datasets import load_dataset
ds = load_dataset(
"Savannah-y7/Genres",
split="test"
)
sample = ds[0]
image = sample["image"]
prompt = sample["text_prompt"]Each pair includes an image, prompt, age group, relationship, scenario and character names.
GENRES uses paired male and female characters for controlled directional comparisons. It does not represent non-binary and gender-diverse identities. Names and scenarios primarily reflect Western/U.S. contexts. Results should be interpreted within this scope, and the benchmark should support broader analysis rather than serve as a standalone measure of fairness.
Use in your research
If GENRES supports your research, please cite our paper.
@inproceedings{xu2026genres,
  title = {From Individuals to Interactions: Benchmarking Gender Bias in
           Multimodal Large Language Models Through the lens of Social Relationship},
  author = {Xu, Yue and Wang, Wenjie},
  booktitle = {Conference on Language Modeling},
  year = {2026},
  url = {https://arxiv.org/abs/2506.23101}
}
The Paper button links to the COLM 2026 camera-ready version. The arXiv link points to the public preprint.